18 September 2012

Lattice Theory for Programmers and Non Computer Scientists


Part One: Mathematical Foundations


Matt Might has a blog post "Order Theory for Computer Scientists" in which he concisely outlines some basics of order theory.  It is a nice post but it is targeted towards computer scientists and is possibly only of interest to that audience, especially since all of his examples are in Haskell, not that there is anything wrong with that, but I think this is unfortunate as these ideas are potentially interesting to programmers as well.


In this post I am mostly talking about lattice theory as opposed to the more general order theory. While general order theory is both interesting and relevant to programming and CS, lattice theory is too and there are many interesting ideas that relate to lattice theory. Lattices impose more structure on orders and that is probably why there are a lot of books on lattice theory such as George Gratzer’s comprehensive and recently updated Lattice Theory : Foundation.  Lattice theory has been described by Gian-Carlo Rota, an accomplished twentieth century mathematician and lecturer, as having "been the object of such vociferous vituperation".  The book Combinitorics the Rota Way, which he coauthored, gives deep insights into this subject and its relationship to other areas of math including, of course, combinatorics, but also topology, set theory, Boolean algebras, probability theory, and more.  I think Rota will be vindicated with a vengeance as it seems to me that lattices show up almost everywhere in math.  Additionally I feel that lattice theory will be become quintessential in computer science and software engineering and should be a mandatory math for those curricula.  I will expand on these ideas in follow up posts.


One anecdote tells of a senior mathematician who stopped Rota in the halls of MIT and stared at him demanding: "Admit it! All lattice theory is trivial."  I confess I have some difficulty with lattice theory as it does seem to be both trivial and deep, at first the ideas don’t seem to really have that much substance, but deeper you dig the more things you find, and it seems that it is always showing up in other areas of math, and even if it is not obvious it often seems to be right under the surface.  I think that’s the duality here, the ideas, per se, are not that impressive, much of the importance comes from the application of the ideas and their relation to other areas of math.


In George Gratzer’s updated Lattice Theory : Foundation he states that a difference between the new addition and the previous edition is the addition of more diagrams, and recommends the reader drawing their own as well, in my opinion he does not go far enough, one of the goals of this post to have some pictures for the basic ideas.  I admit I will do my best here to help the motivated learner, but this post should probably be viewed as supplemental to other resources.  Also you will need to have some knowledge of set theory and concepts like Cartesian products and some knowledge of abstract algebra such as group theory may also be helpful.  Also knowledge of basic graph theory is needed.  You will also need some comfort level with basic mathematical notation.  If you don’t have this knowledge, hopefully you are willing to get up to speed on it, trust me, it’s worth it.  Another point to note is that everything covered here will be finite, all sets, orderings, and lattices are finite, I believe that much of this extends to the countable infinite, etc.  I leave that for you to pursue.


Lattices Drawn as Graphs


Lattices have some connections to graph theory and to really fully understand the nuances of these ideas you need to have an understanding of basic graph theory, specifically the differences between directed graphs and undirected graphs and an understanding of cycles and acyclic graphs.


Lattices can be drawn as graphs the main diagram used to visually represent lattices is the Hasse diagram which depict lattices as a undirected graph, more on this below.  Also it should be noted that issues of graph planarity are ignored and two crossing edges, that is with no vertex, have no significance in terms of order, also sometimes for aesthetic reasons intersecting lines are shown as crossing behind other lines, again this has no impact on the order structure.


Binary Relations


Lattices are built on the concept of a binary relation on a non empty set. This is usually expressed in terms of the Cartesian product of a set with itself, where R is the relation and S is the set:


R : S x S → S


In this case the binary relation emits a member of the same set, which means it is closed on the set.


For example for the set S = {a,b,c} a possible relation is the ordered pairs: R = {(a, c), (a, a), (b, c), (c, a)}.  In general a Binary Relation can be written as a set of ordered pairs.  When talking about orders there is a distinction as to whether the relationship between two elements in the set exists, meaning does the ordered pair (x,y) exist in R.  In the example above (b,c) exists, (b,c) ∈ R. Also note that opposite relation of (b,c), (c,b) is not in R, (c,b) ∉ R.


This binary relation can be seen in the diagram below, each of the ordered pairs map to a directed edge:


Properties of Binary Relations


Binary Relations can have certain properties.  I feel this is the crux of understanding ordering relationships.  The first two properties are:


Reflexive ∀x ∈ S (x,x) ∈ R

Transitive∀ x,y,z ∈ S if (x,y) ∈ R  and (y,z) ∈ R then (x,z) ∈ R


If a binary relation has these two properties, that is it is Reflexive and Transitive then it is known as a preorder or quasi-order.  This is a more general type of binary relation which we are not really interested in initially except in how it relates to two more specific types of binary relations.


The symmetric property is defined as:


Symetric ∀ x,y ∈ S if (x,y) ∈ R  then (y,x) ∈ R


A preorder with the symmetric property is known as an equivalence relation.  In terms of Lattice Theory this is another binary relation that we are not immediately interested in.  Equivalence relations are well worth learning more about in their own right, as they play an important role in partitioning sets which have interesting applications in abstract algebra in relation to quotients of groups and rings and homomorphisms of groups and rings.


The next property, which we are very interested in, is the antisymmetric property which is defined as:


Antisymmetric ∀ x,y ∈ S if (x,y) ∈ R and (y,x) ∈ R then x = y


A preorder with the antisymmetric property is known as an order relation sometimes referred to as a partial order. A set with a partial order on it is called a partially ordered set, poset, or just an ordered set.  So now we have a definition of an order:


If S is a non-empty set then by an order on S we mean a binary relation on S that is reflexive, anti-symmetric, and transitive.


We will now use the less than equals symbol ≤ to denote our order relation which follows as:


(∀x∈ S) x ≤ x;                                     (reflexive)
(∀x, y ∈ S) if x ≤ y and y ≤ x then x = y;      (antisymmetric)
(∀x, y, z ∈ S) if x ≤ y and y ≤ z then x ≤ z.(transitive)

In general an order is defined using the notational convention: (S, ≤) where S is the Set on which  the order is defined and ≤ denotes ordering relation.  Note:  ≤ is not necessarily the same as less than or equals, it might be, but it could also be a number of other order relations.


Comparability: Partial Orders, Total Orders and Antichains


One thing that I found confusing when learning about ordering relations is the difference between a total order and a partial order.  The idea of a partial order is that not all elements in a set have a relation.  Some pairs of elements are incomparable, meaning no relation exists between them.  This is denoted using the parallel lines symbol: ∥, for example x ∥ y means (x,y) ∉ R and (y,x) ∉ R. 


An example of a partial order is the set of partitions below:


This is a partial order of set partitions of a set of three items.  For example suppose that the set {a,b,c} is a plate containing an apple, a banana and a cherry.  As you move down the lattice you get more partitions, in the second row you can partition two pieces of fruit onto one plate and one on another, in three different ways {a}, {b,c}  or  {b}, {a,c}  or  {c}, {a,b} .  In the bottom row you can only partition three pieces of fruit one way on three different plates {a},{b},{c}.  If you move up the lattice you can reverse the operation and consolidate the set partitions (plates) in the same manner. 


You should note that above the elements:  a|bc,  b|a,c, and c|a,b have no ordering relation to each other, that is there is no way to further partition the current plates, rearranging them isn’t allowed. So these items are incomparable: a|bc  ∥  b|a,c,   b|a,c  ∥  c|a,b , ...


A total order is also known as a linear order or a chain. In a total order all elements are comparable meaning that the relationship has the following total property:


Total ∀ x,y ∈ S  (x,y) ∈ R  or  (y,x) ∈ R


A fairly simple example of a chain is the integers 1-5 with the ordering relation less than or equals, which would be written as ({1,2,3,4,5}, ≤) which would have the following diagram:


An antichain is a set where no two elements are comparable:


Antichain ∀ x,y ∈ S  (x,y) ∉ R  and (y,x) ∉ R


An example is the suits of a card deck, there are probably some exceptions, but in general a spade, a heart, a club and a diamond have no order relation to each other, this antichain can be depicted as:


Also you should note that above the elements:  a|bc,  b|a,c, and c|a,b in our set partition lattice above form an antichain within that lattice.


Order Duality


Order duality is actually a fairly intuitive idea, for example if you had a list of words in alphabetical order, you can reverse the order. This holds true for every ordering relation and is called the Duality principle.  More formally if you have an order P = (S, ≤), its dual denoted Pd would be defined as Pd =(S, ≥).  If you take any of the lattice examples above or below and reverse them, flip them upside-down, you get the dual of the order relation.  This is one of the most seminal ideas in order theory. It also shows up in other parts of math.


The Powerset Lattice


The powerset of set is a set of all of the subsets of the set.  For a set of three items, S = {a,b,c} The power set of S, which is a set of sets, is: { {a,b,c}, {a,b }, {a,c}, {b,c}, {a}, {b}, {c}, ∅ }.  A common notation for denoting the powerset is 2S.  This notation draws from the fact that the cardinality of the powerset is the cardinality, the size of the set, of the set raised to the power of 2, this can be expressed more concisely using the notation |S| to describe cardinality, so the above set has the cardinality |S| = 3. The powerset of S 2S has the cardinality |2S | = 23 = 8.


The lattice below shows the ordering relation "is a subset of", this can be denoted by ⊆ and the order would be given in notational form as (2S, ⊆).


Its order dual which is "is a superset of" given by (2S, ⊇):


Binary Relations Drawn as Graphs


Now that we have some definitions and diagrams in place I wanted to revisit the drawing of lattice diagrams.  Our first relation diagram above has a loop for (a,a) and (b,c) (c,a) makes it transitive, but it is not reflexive because it is missing loops for b and c.  So that relation is not a preorder which means it is also neither an equivalence relation nor an ordering relation.


For every preorder, there corresponds a directed graph, with elements of the set corresponding to vertices, and the order relation between pairs of elements corresponding to the directed edges between vertices.  Graphs of preorders can contain cycles.  Also all nodes in a preorder group will have a loop for the reflexive relation that must exists on each node.  Graphs representing equivalence relations will be undirected graphs since these relations are symmetric and will of course have loops on each vertex for reflexivity.   As mentioned above graphs for partial orders will be a directed acyclic graph graph due to antisymmetry also they should have reflexivity loops.


The total order for 1-6 mentioned above would look as follows for the relation ≤ it is a simple directed graph:
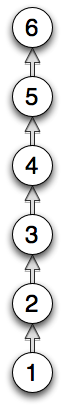


If we were to add all of the transitive and reflexive relations it would look like this:


As we have seen in our diagrams the reflexivity loops are omitted as they are not needed and would be increase the complexity of the diagrams.  Also in the diagrams the transitivity can be inferred by following the two paths connecting three nodes.


Hasse diagrams are drawn as undirected graphs which implies the order duality, we can decompose that graph into two directed graphs as in our example above for the two dual realtions (subset ⊆ and superset ⊇) on the powerset lattice, the lattice is conventionally drawn as the following Hasse diagram: 


Another interesting point here is the difference between equivalence relations and order relations is that no cycles will occur in an ordering relation.


Subsets of Posets


Since we are dealing with sets, a set with an order relation, a poset (short for partially ordered set), can have subsets.  The interesting thing is that the subsets as a whole can be different types of orders than the original poset.  For example the power set above has as a sub-poset, {a,b,c}-{a,b}-{a}-∅, which is a total order.  Additionally the antichain {{a,b}  {a,c}  {b,c}} is also a subset of the powerset poset.  These elements still have the same relations as they did in the original set, but the subsets themselves are different structures.


Upper and Lower Bounds


A finite set, remember we are only considering finite sets, with an order relation implies that if you move up and down the ordering relation eventually you will hit a maximum or minimum element.  The above examples, the total order has an upper bound of 5 and lower bound of 1, the powerset lattice has an upper bound of the set itself and the empty set as a lower bound.  The antichain does not have a single upper or lower bound the four elements are each both their upper and their lower bounds.  The idea of bounds, specifically the idea of greatest lower bound (GLB)  which is also known as an infimum and the dual the least upper bound (LUB) which also known as the supremum are important in order theory but show up in other areas of math such as topology.


A poset may not have one upper or lower bound, this is a distinction from a lattice which is still a poset but it has a single upper and lower bound.   A lattice will have both a distinct upper and distinct lower bound, that is one element that is the upper bound and one element that is the lower bound. These are sometimes denoted as ⊤ for upper bound and ⊥ for lower bound.  This bounding feature of lattices is very important as we will see.


The Samuel L Jackson Lattice (Total Order)


Since Samuel L. Jackson has a habit of showing up everywhere, he is the new Kevin Bacon, and it is only fitting that he would show up in Lattice Theory.  Another example of a total order or chain is what is known as the "Samuel L. Jackson Scale of Black Emotion" which was developed by Larry Willmore of the Daily Show.  It forms a Total Order also known as the Samuel L Jackson Lattice, which includes the following elements:


  • Furious Anger Guy
  • Shaft
  • Changing Lanes Guy
  • Snakes on a Plane Guy
  • Jurrasic Park Jackson
  • Frozone
  • Mace Windu

As you can see the sup(Samuel L. Jackson Lattice) = ⊤ = "Furious Anger Guy" and the inf(Samuel L. Jackson Lattice) = ⊥ = "Mace Windu". Now it’s pretty obvious in an intuitive human sense that the Master of the Order and Jedi Master Mace Windu is the lattice dual of Furious Anger Guy of Pulp Fiction, well up to his epiphany in the diner robbery scene anyway.


As with all lattices, this lattice has an order dual denoted (Samuel L Jackson Lattice)d known as the Inverse Samuel L Jackson Lattice, which just a reverse of the above list.


Ok, I’m having a little fun here, trying to lighten the mood a little.  However, this is a legitimate example of a lattice.


Lattices vs Posets


By definition a lattice is a poset, however, a poset is not necessarily a lattice.  A lattice is defined as, with sup being supremum and inf being infimum:

An order (S,≤) is a lattice if sup{a,b} and inf{a,b} exist ∀ a, b ∈ S.


Actually there are some distinctions between different classes of lattices:


A lattice is a poset in which all nonempty finite subsets have both a least upper bound and a greatest lower bound.

A complete lattice is a poset in which all subsets have both a least upper bound and a greatest lower bound.

A bounded lattice has a unique top element and a unique bottom element, actually there are algebraic implications that we will discuss below.

Finite sets form complete lattices and since we are limiting ourselves to finite sets we will only be dealing with complete lattices. Also every complete lattice is a bounded lattice so when we talk about lattices here we will mean complete lattices aka bounded lattices.


Up and Down Sets


If you take an element of a poset or a Lattice and take the subset of all elements that are greater than the element you get a new poset or lattice that is a subset, these types of subsets are referred to as up-sets or down-sets. An up-set of an element x denoted as ↑ x includes the element and everything above it is defined as:


↑ x = {y∈ P : y ≥ x}


The up-set of the element {a} in the powerset lattice above would look like (shown in blue):


Similarly, or perhaps "dually" the down set, denoted as ↓ x, is defined as:


↓ x = {y∈ P : y ≤ x}


With the down-set of the element {a,b} in the powerset lattice (in red):


Meet and Join


Meet and Join are two binary operators defined on elements of posets and and lattices which yield a unique value and they are dual operations of each other.  In the case of a poset meet and join may or may not exist on any two elements, in the case of a bounded lattice they will exist.  Join is usually denoted with the or symbol: ∨ and meet is denoted with the and symbol: ∧.  Join is equivalent to supremum and meet is equivalent to infumum. They are defined as: 


x ∨ y = sup{x,y}

x ∧ y = inf{x, y}


The following describes their relation with ordering:


x ≤ y  ⇔ x ∨  y = y

x ≤ y  ⇔ x ∧  y = x


As you can see above when two elements are comparable meet and join will reduce to the appropriate minimum or maximum element, when two elements are incomparable as in the picture of the join below between {a} ∨ {c} the lattice lines show how the join moves up to the element {a,c} that is above each element, not coincidently the join on this lattice is the set union operation ∪ actually this join can be expressed as {a,c} = {a} ∪ {c} which is right out of set theory.


And the dual relation is {a} ∩ {c} = ∅:


Semilattices


A semilattice will define either a meet or a join operation over an order resulting in either a meet  semilattice or join semilattice, technically a lattice is both of these combined. A good example is a tree which as a single root node, let’s call it a lower bound aka an infimum, a common example is the prefix tree for strings, in this case we are using binary strings 0 or 1 up to length three:


In this example the order relation is: "Is a prefix of".  As you can see you can define a meet on any two elements with the empty string λ serving as the semi-lattice bottom ⊥. Also as you can see there are no joins on this order.  Pretty much any tree can be viewed as semi lattice with descendency from the root node through all of the other nodes serving as the ordering relation.


Lattices are Algebraic


One of the interesting and sometimes confusing things about lattices is that, while they are structural they are also algebraic.  Meet and join follow a number of algebraic rules.  In general lattices can be defined as an algebra L=(S, ∧, ∨) which satisfy the following algebraic rules for all x, y, z ∈ S:


Idempotent

x ∧ x = x

x ∨ x = x,


Commutative

x ∧ y = y ∧ x

x ∨ y = y ∨ x,


Associative


x ∧ (y ∧ z) = (x ∧ y) ∧ z

x ∨ (y ∨ z) = (x ∨ y) ∨ z,


Absorption

x ∧ (x ∨ y) = x

x ∨ (x ∧ y) = x.


The first three pairs of axioms say that L is both a meet and join semilattice. The fourth pair (the absorption laws) say that both operations induce the same order on L.


Since we are dealing with bounded lattices we extend the above laws to include the following for the top and bottom elements, here we will represent the bottom element ⊥ as 0 and the top element ⊤ as 1.  For a bounded lattice the algebra is defined as L=(S, ∧, ∨, 0, 1) with the following identity laws:


x ∨ 0 = x

x ∧ 1 = x

x ∧ 0 = 0

x ∨ 1 = 1


For our powerset lattice above the algebra is (S, ∩, ∪, ∅, S) with the empty set as the identity for the union operation and the set itself as the identity for the intersection.


Other Lattice Properties and Operations


If you take our powerset example above, you might have noticed that there are some more algebraic properties of this lattice that are not listed above.  The first is the distributive property.  While the powerset lattice does have the distributive property you should note that not all lattices do.  The distributive property is defined as:


Distributive Law

x ∨ (y ∧ z) = (x ∨ y) ∧ (x ∨ z)

x ∧ (y ∨ z) = (x ∧ y) ∨ (x ∧ z)


Another property which can be found in certain lattices and also applies to our powerset lattice is the property of complementation which means that for every element x the lattice has a complement y under both the meet and join operations:


x ∧ y = 0

x ∨ y = 1


Some Lattice which are Complemented can have additional properties which is known as orthocomplementation and has the following laws:


Complement Law

x ∧ xc = 0

x ∨ xc = 1


Involution Law

(xc)c = x


Order Reversing

x ≤ y then yc ≤ xc


Our power set lattice which is also a Boolean Algrebra also follows Demorgans laws:


Demorgans laws

(x ∨ y)c = xc ∧ yc

(x ∧ y)c = xc ∨ yc


Some lattices can have a property known as Modularity which follows the following law, which is similar to the distributive law:


Modular law

x ≤ z implies x ∨ (y ∧ z) = (x ∨ y) ∧ z


I am including Modularity for completeness as I am not discussing it or including examples.  Distributivity, Modularity and Complementation have many intricacies and there is much theory and complexity surrounding how these work and where they show up, this becomes quickly obvious if you dig into more resources on lattices.


The Algebraic Structure of the Powerset Lattice


With the above algebraic laws of complemented (orthocomplemented) bounded lattices defined, I figured it might be nice to list out these laws as they apply to our powerset lattice, if we take the powerset 2S of any set S, the empty set ∅ is the lower bound and the set S is the upper bound. The powerset lattice has the following laws:


Idempotent

x ∩ x = x

x ∪ x = x


Commutative

x ∩ y = y ∩ x

x ∪ y = y ∪ x


Associative

x ∩ (y ∩ z) = (x ∩ y) ∩ z

x ∪ (y ∪ z) = (x ∪ y) ∪ z


Absorption

x ∩ (x ∪ y) = x

x ∪ (x ∩ y) = x


Distributive

x ∪ (y ∩ z) = (x ∪ y) ∩ (x ∪ z)

x ∩ (y ∪ z) = (x ∩ y) ∪ (x ∩ z)


Identity

x ∪ ∅ = x

x ∩ S = x

x ∩ ∅ = ∅

x ∪ S = S


Complement Law

x ∩ xc = ∅

x ∪ xc = S


Involution Law

(xc)c = x


Order Reversing

x ⊆ y  then  yc ⊆ xc


Demorgans laws

(x ∪ y)c = xc ∩ yc

(x ∩ y)c = xc ∪ yc


The D4 Dihedral Subgroup Lattice


This topic might be filed under an advanced example, so feel free to skip if you’ve had enough for the moment.  In doing my research I came across the following lattice diagram, it is the lattice of the subgroups of the D4 Dihedral Group, I looked at cyclic groups and subgroups including the cyclic subgroups of D4 in a previous post on abstract algebra.  I have modified it to better show the identity element marked in blue. It also includes the names of well known isomorphic groups that correspond to each subgroup.


This lattice shows some really interesting things about the dihedral group. The top element is the D4 group itself and the bottom element is the trivial Z1 group consisting of only the identity. As you can see the center forms a chain consisting of three cyclic groups, Z1, Z2, Z4, and D4 (not cyclical). The anti-chain of five Z2 isomorphic groups, all of which are involutions, like negation it is an operation which if applied twice results in the original value, on the left are the horizontal (H) and vertical (V) reflection involutions, the middle one is a 180 degree rotation (R2) involution and on the right are two diagonal (D1, D2) reflection involutions. As you can see on the vertical and horizontal involutions on the left along with the rotation involution form the group (R0, V, H, R2) and on similarly on the right the subgroup (R0, D1, D2, R2) is formed. Also both of these groups are isomorphic to what is known as the V group, aka the four group, aka Klein group, aka the Vierergruppe. I am not sure what all of this means but I find it fascinating. Also please note that there is a minor nomenclature conflict as V refers to both the Klein group and the vertical reflection D4 group element, but the context of each is mutually exclusive. The same goes for Dn where D1 and D2 are elements and D4 is a group. Additionally this lattice give a nice visual depiction of Lagrange's Theorem which states that the order of each subgroup will evenly divide the order of the group. Therefore, as in the lattice, a group of order 8 only has subgroups of orders 4,2,1.


Some Notes on Notation


In math notation can vary and order theory has several variants on notation that it helps to be aware of.  Firstly the following sets of symbols can often be used in relations to orders:


Sometimes these choices are made at a particular authors preference other times combinations of these are used, such as in discussing things like Galois Connections which are mappings between two different orders, in such a case multiple sets of the above symbols might be needed to differentiate between specific instances of different orders.  Usually the set notation symbols are not used for lattices but they sometimes are, and in our examples above both meanings apply.  Also the following symbols get used to describe comparison as well:


Another set of symbols that show up, which are often used to describe covers, or immediately precedes or immediately succeeds, in that there are no elements between the two items compared are:  


Additional Topics


The topics of lattice theory and order theory are extensive and this post really just scratches the surface.  When you feel comfortable or even if you don’t depending on your learning style, there are many things that I did not cover.  There are order specific concepts like strict and asymmetric. Complete partial orders show up a lot in CS as well.  For lattices there are things that I only mentioned like modularity and Galois connections, there functions on lattices which include ideas like monotone, antitone, and isotone.  New lattice can be created by number of techniques like the Cartesian product of two lattices.  And of course there are many interesting results relating to fixed points, and the list goes on.


In my next post I will look at some specific examples of some the ideas discussed here in everyday programming and some more theoretical examples as well.


References and Resources


There are a number of books on the subject, including the previously mentioned  the recently updated Lattice Theory: Foundation  by George Grätzer and Combinatorics: The Rota Way by Joseph P. S. Kung, Gian-Carlo Rota and Catherine H. Yan, there are a number of books on the subject including:


  • Lattices and Ordered Algebraic Structures by T.S. Blyth
  • Introduction to Lattices and Order by B. A. Davey and H. A. Priestley
  • General Lattice Theory (Second Edition) by George Grätzer, B.A. Davey, R. Freese and B. Ganter

If you are just getting into the subject, and even if you are not, I would recommend taking advantage of some good free resources, listed in no particular order:


Lattice Theory with Applications  by Vijay K. Garg

Notes on Lattice Theory[complete pdf here] by J. B. Nation of the University of Hawaii

Chapter 1 - Lattice theory in Vaughan Pratt’s CS 353: Algebraic Logic course handouts

Dave Abrams "Order I Say" blog post, some of the above images are from his post, with his permission, thanks.

Lattice Tutorial by Nenad Jovanovic of Secure Systems Lab

Lecture 7 and lecture 8 of Lionel Levine’s course on Algebraic Combinatorics

Chapter 2 - Ordered Sets and Complete Lattices, A Primer for Computer Science by Hilary A. Priestley of  the Mathematical Institute, University of Oxford

The Many Lives of Lattice Theory by Gian-Carlo Rota

Wolfram’s Mathworld on lattices

07 August 2012

Why You Can’t Have a Real Software Engineering Discipline


As we all know the fields of computer science and software engineering are in their infancies.  Many a blog post has been written lamenting the fact that software engineering is not a real engineering discipline, and while I have not written that exact post, I have written about the subject and have deconstructed what others have said about it.  A number of these points do apply to why software projects routinely fail, yet another topic that has received considerable attention.  Now admittedly all engineering disciplines regardless of their maturity and formalization have project failures and creating a real software engineering discipline will not eliminate this problem but one would hope that it would abate it.

I find it odd that at a time when so many people are involved in IT there seems to be little discernible progress in creating a real software engineering disciple.  There are probably millions of people working on creating software.  Also there are many researchers trying to solve this problem from many different angles.  Practitioners have been attempting to solve it with ideas like Agile and Software Craftsmanship, etc.  Additionally there is a long list of failures surrounding the formalization software engineering.  

My biggest complaint is the fact that there really are no good formal standards in general software engineering principles and methodologies lack a formal foundation and even the more vague principles can be easily thwarted and misused, and often, as I have previously complained, it often ends up being based on pure opinion which is usually won through positional authority, perseverance or by those who are just more politically savvy.

The intent of this post is not to attempt to solve or even offer solutions to the problem of creating a real software engineering discipline but to look at what I think are some barriers to creating this discipline and in some of these cases offer thoughts on overcoming those barriers.


Low Entry Requirements


If we are to think software engineering as an engineering discipline, I challenge you to find another engineering discipline that routinely has practitioners with no formal training in the field.  I very much doubt that someone who did not hold a degree in engineering and who built a shed in his back yard is now working as a structural engineer on a construction project, the mere idea seems ludicrous.  Yet I have worked with non technical degree holders who became software developers, one who started by building web pages and now calls himself an "Internet Application Architect", and is probably one of the biggest cargo cult coders I’ve ever had the misfortune to work with.  This egalitarian aspect isn’t all bad as it does let good people into the field as well.   Another non technical degree holder I once worked with became an accomplished developer and went on to get an advanced degree in CS and is now a CS professor.   Although it’s probably the case that for every good non technical degree holder who joins the field it is likely that dozens of mediocre and bad practitioners will also join.   It seems that in other engineering disciplines there are much more stringent educational requirements to ensure proper training.   To be clear here I am not equating having a degree with being competent because I have met many incompetent people with degrees, but still you need something.   I confess I am at a loss for a solution for this one.


The Lack of Differentiation between Science and Engineering


Chemistry is a scientific discipline, chemical engineering is an engineering discipline, and you can make this comparison between other engineering disciplines and the sciences that they employ e.g. electrical, mechanical, and structural map to various areas of physics.  Engineering and scientific disciplines are different types of disciplines often taught in separate schools.  Although each engineering discipline has some scientific overlap and it would probably be possible to move from the appropriate scientific field to the corresponding engineering field in general you probably would not do so without returning to school.   In recent years software engineering curricula have been added to the rosters of many colleges and while this is potentially a step forward, discounting for the moment that software engineering is still not really real engineering, a software engineering degree and a computer science degree in many cases gets you the same job!   

So in other fields there would be a differentiation between a degree that would put you on a track to do scientific research and one that would put you on a track to do engineering work.  As I understand it, if you are fresh out of school with a BS in CS that qualifies you to be a tester at Microsoft1, developers hired right out of school need at least a Masters degree in CS.   This is an extreme case of how this really breaks down in our industry.  In most cases engineering practitioners are the software engineering, MIS, CS or even non technical degrees and the few scientific careers generally go to the advanced degree holders.  I admit this probably fairly normal a BS in chemistry or biology is also more likely to get you a job in IT than a job as a research scientist.  Still compared to more mature engineering fields there seems to be a lack of real differentiation between the degrees that yield a career as a software engineer versus one as a computer scientist.


Bad Management


The entry requirements for managers in software make the low entry requirements for software engineering practitioners look downright rigorous.  I have previously criticized the fact that many organizations find the cheapest people, especially for software management and give them an obligatory certification.  Now I know that engineering management regardless how formal or established the engineering discipline is an area that has problems and failures, but again I very much doubt that you would find a twenty something business or liberal arts major with a freshly minted PMP suffix managing construction or civil works projects.   Yet in my experience this is pretty normal in IT especially in the government sector.  Of course bad software management is executed by older managers as well.

A post by Larry White titled "Engineering Management Is Dying" delves into some these issues.  It is definitely the case that methodologies like Agile have changed how software projects work and the traditional corporate management approach to software really doesn’t work.  One point he makes is that it is not uncommon to see a two hundred person project at Google headed by an engineer.  To me this implies that someone is in some way managing that project.  I think all of this is indicative of the need for software engineering mangers to also be practitioners in engineering or at least very well versed in how software development works.  The situation he talks about at Google is not the case everywhere, in that case the company is its own client, but there are many cases where software is being built for clients and this does create a need for management that deals with the client, perhaps this should be a role that is separated from management and called a client liaison, which is what often happens.  Also I am not sure how things work at Google but I have also seen internal development in organizations where the IT department provides services to an internal client, I have also seen this go horribly awry with contentious unproductive relationships between departments.  In short I feel that just as we need a real software engineering discipline we also need a real incarnation of software engineering management.


The Disconnect between Academia and Industry


Most practitioners do not keep up with, or read academic research, actually many practitioners don’t read at all, but that’s another issue, and most academicians don’t work in the field so they lack the hands on knowledge.  Unfortunately this rift can take on a somewhat disdainful tone as is the case in my exploration of one practitioner’s attempt to define "Real Engineering".   Fortunately some people, I’d like to count myself among them, take a more constructive approach to building bridges across this rift.  Daniel Lemire has an interesting critique the quality of software produced in academia. 

I think the solution here is for both sides to become more engaged in problems faced on each side. I am optimistic about this one as I feel that these walls are breaking down as the field is growing up and many of the emerging technologies are forcing developers to be more cognizant of and engaged in research topics.  I also have encountered much more research that has ties to the practical concerns of day to day software development, some I have mentioned with more to come.


The Lack of an Effective CS Math Curriculum 


If you read my blog you know it to be a mix of math and software practices. I would describe myself as a software practitioner and a math enthusiast.  My math journey has taken me on some interesting math excursions into areas of math that seem to get little or no mention in CS curricula and I feel that this is a major problem in really applying math to the field of software engineering.  Another problem is in the way that it is taught, my experience was that it was not only taught badly but in a way that made it seem irrelevant to many of the programming courses.  Specifically I would shift the CS math curriculum to include less differential and integral calculus and include more logic, combinatorics, abstract algebra, graph theory, order theory, category theory and probably some topology among others.

Over the last few years I have been progressively learning more math which has been in part motivated by necessity for understanding research papers.  This approach has changed the way I see things, I now see the patterns of math in software. They are there and I believe that they can be exploited to create a real software engineering discipline.

For the math learning problem I do have some ideas many of which are expressed in my blog.  Some of my posts like refactoring if statements with Demorgan’s Laws or the String Monoid, the Object Graph, etc. are about making these mathematical ideas more relevant and accessible to programmers. Other posts like my series on naming and my post on generic programming and entropy and complexity are about my own ideas and ideas in the research literature that I feel may help to create a real software engineering discipline.  These are my attempts at solutions to these problems, so expect more of both of these and more thoughts on the CS math curriculum.


The Software Architect Debacle


This is one that really bothers me.  I feel the software architect role in general has a very negative effect on creating quality software and it dissuades the industry from developing a real engineering discipline.  The Software Architect role tends to be broadly defined, you have enterprise architects, software architects, etc., some architects tend to be involved with hardware and networking, some work on configuration management, some do software design, some do all of these things and more.  I feel this is a problem as each of these is a separate engineering area with different types of problems. By not breaking these down it often leads to a lack of focus on specific problems, also I have seen cases where the architect focuses on their preference and ignores other issues.  The architect role is often divorced from the code.  I have met many architects that were responsible for software but had never even looked at the code.  To me this is a huge failing that architects that are responsible for building software often lack the interest, time, or even aptitude to know the quality or underlying of structure of the software that they are delivering.

To really do justice to these ideas I might need a separate post, my solution would be to break down the architect role into specific engineering roles, which could include:


  • Software Process Engineering - this would be involved with software team and resources planning, some aspects of configuration management such as defining policies, requirements analysis and general project management aspects of software construction including the definition and refinement of the SDLC.  This role is tightly coupled with software engineering management.
  • Software Structural Engineering - this would include requirements comprehension, code infrastructure planning, prototyping work, hands on code structural work including custom frameworks and reusable components, third party library products, and general code quality including reviews and static analysis.
  • Software Quality Engineering - This would include the QA roles, software testing and testing tools, requirements validation and refinement, usability and reliability and general software quality issues.
  • Software Infrastructure Engineering - This would include hardware, networking, database, app server and general service infrastructure, non functional requirements fulfillment and possibly the implementation of configuration management, continuous integration, etc.

This is a rough "sketch" of these possible roles and each of these areas has some overlap implying that all of the people in these roles would work closely together, also some combination of, or all of these roles might be performed by a single individual depending on the organization’s size and structure.  What this approach does is clearly defines roles and responsibilities as opposed to some nebulous software architect role.


The Continuous Turnover of the Work Force


A young CEO once commented that he thinks young programmers are superior.  In general companies prefer younger workers as they often don’t have family commitments so they can work more hours and you can pay them lower salaries, DC area government contractors rely on this to keep their profit margins up.

As an older developer I often find this frustrating.  I confess that I have not moved up the ladder and still mostly work as a developer or what might be called a hands on architect, yes I know but that’s the current term, actually my preferred title would be: Software Structural Engineer.  Working as a contractor I have on several occasions found myself on projects that were dominated by younger developers and unfortunately on more than one occasion I watched as teams would make many mistakes due to a lack of experience, in some cases I was able to help in others I was ignored by the younger developers.  This is not to say that I do not still make mistakes, I’ve just been around long enough to have made a lot of them already.

If you buy into the software craftsmanship thing, I admit to being skeptical of this idea, you might be inclined to draw a parallel to craftsman of the past when older established masters took on apprentices and passed on their wisdom to the next generation.  Given the access to information these days such process is somewhat antiquated and perhaps impractical.  Nevertheless I feel, and the industry supports me here, that older developers who keep their skills up to date have value.  I know several younger developers who have sought me out to learn from me so I think I can safely say I still have some value.

Many older developers have let their skills get rusty and have not kept up on current technologies I have seen this many times.  Also many companies seem to lack the vision to allow for real hands on technical career growth.  I can’t help but feel that this inclination to recycle developers in each new generation is hurting or at least slowing our ability to develop a real software engineering discipline, this potential loss of continuity seems like it leads to some lost wisdom.


The Social Networking Drain and Hollywoodification of Silicon Valley


As I write this Hollywood gears up to deliver a reality TV show that takes place in silicon valley and Mark Zuckerberg now gets the paparazzi treatment.  Another article that I previously mentioned was about how CS enrollment was up because the movie The Social Network had enticed many aspiring Zuckerberg wannabes.  At present there does seem to be a gold rush mentality and it is noticeable and even discussed on sites like Hacker News. 

As someone who has never worked in the valley I am very much an outsider and may not have a good perspective on these things, but it seems that there are a lot of startup companies focusing on crap. Now I get it.  We live in a shallow consumer society with a rapacious appetite for crap. But are not these supposed to be some of the smartest people and I am not the only one to wonder why so many smart people who should have better taste and higher standards are settling for working on serving up ads and other vapid crap instead of doing more meaningful work like working on real problems that would advance human society or even just work on advancing software engineering. 


1I believe this was the case in the late 90’s and may have changed, this information was conveyed to me by a former Microsoft employee.


17 July 2012

A Framework for Software System Naming

On the Importance of Naming in Software Systems part IV


In my previous posts on naming I have laid the foundation for a framework for naming in software systems.  This post is mostly a rehashing of those previous ideas and is intended to both codify and consolidate the definitions of terms upon which I have chosen and created to build a naming framework.  It also serves as a single location to concisely reference these ideas.  To gain more insight into the background and development of these ideas see my previous three posts:  "A Survey of the Conventional Wisdom on Software Naming",  "More Thoughts on Formal Approaches to Naming in Software", and "Software System Morphology".  The definitions are as follows:

Structural

  • Name – The Signifier that consists of a string of characters that refers to a System Referent.
  • Name Unit Separator – is a mechanism to separate name units within a Name, this can be an explicit character such as "-" or "_".  It can also be in implicit mechanism such as the use of Camel Case within the name.
  • Name Unit – Is the smallest lexical unit of a Name usually separated by a Separator (Name Unit Separator) and is used to describe the lexical structure of the Name.
  • Named Scope Context – this is the location of the Name within the system, e.g. where the name usage occurs.
  • System Referent – This is the actual instance of a thing that is named and is used in the system. See System Referent Type for specific types of System Referents.
  • System Referent Type - This is the specific type or class, as in classification, of what a System Referent is in a system some examples include:
    • Classes
    • Variables (local, instance, static)
    • Methods
    • Method Parameters
    • Packages
    • Database Tables, Columns, Triggers, Stored Procedures, etc.
    • HTML Files, CSS Files, Javascript Files, Config Files, all files
    • Directories
    • Urls
    • Documents
    • XML Elements and Attributes
    • CSS Classes

Semantic


  • System Morpheme – This is a conceptual unit of meaning in a system that is used in a name, it is distinguished from a Name Unit in that a morpheme can consist of one or more Name Units.
  • System Natural Language Set – This is the set of Natural Languages used to create the names.  It is often English but it need not be and a system could include components or be constructed in a way that might include hybridization between multiple natural languages.
  • Problem Domain - This is the Semantic Domain that describes problem area for which the system solution is targeted.  This would be a set of concepts and System Morphemes that apply to the problem domain. For example a financial system would be built using the relevant financial terms and language concepts.
  • Solution Domain – This is the Semantic Domain that describes concepts that are used to implement the system including System Morphemes that apply to the solution domain.  This might include things like terms that describe Design Patterns, data structures, etc.

As you can see from above these Ideas can be separated into two categories: Structural and Semantic. However the two categories are not completely independent of each other so there is some overlap and interdependence.  The structural ideas include: Name Unit, Named Scope Context, System Referent, and a System Referent Type.   Each Name has these properties as attributes.  A name has a lexical structure made up of Name Units, and refers to a System Referent of some System Referent Type and has one or more locations given by its Named Scope Context(s).

The semantics of the names which has the "unit" described by the System Morpheme idea has semantic properties which will fall into either the Problem Domain or the Solution Domain.  The expression of these concepts is dependent on the System Natural Language Set, in other words the natural languages that are used to construct meaningful names for concepts in both the Problem Domains and the Solution Domains.

This is the current state of my thinking on this. These ideas will be refined and might change over time, the objective is to develop something that is useful and that both supports and can be validated by a more analytic approach.

15 July 2012

Renaissance 2.0


Are We on the Verge of the Next Renaissance?


On 31 October 1517, Martin Luther sent to his bishop Albert of Mainz a copy of his "Disputation of Martin Luther on the Power and Efficacy of Indulgences", which came to be known as The Ninety-Five Theses.  In January of 1518 he also sent copies to his friends who translated it from Latin to German and had copies printed and passed them on.  In part because of easy mechanized printing it went viral, within two weeks it had spread throughout Germany and in a month throughout all of Europe. The rapid propagation of his leaked private communication caught Luther by surprise and he soon found himself in a full on “flame-war” directly with the Pope.  Luther quickly mastered this new mass media and effectively used it in his fight.  This early landmark public dispute in the emergent mass media of the time demonstrated a new power structure built on the rapid spread of ideas.

Guttenberg’s motivation for inventing the printing press, an idea that had also been invented previously in Asia, was strictly entrepreneurial and it was not his first venture. Shortly after the introduction of the printing press to Europe, other entrepreneurs realized that there was a demand for books.  In some respects the printing business of the late 15th and early 16th centuries was very similar to the internet boom that we are currently experiencing.  This new technology not only caused the creation of new businesses but it also transformed the dissemination of information and the power of information itself in the sense that new information could be more easily created and collaboratively built and referenced also language was standardized and local vernacular languages replaced Latin for scholarly works.  This new more egalitarian access to books and information fueled the spread of ideas, and caused an exponential surge forward in the ability develop science and technology and culture itself.1

There was a dark side to this new change in the way information was disseminated. The Catholic Church, which held a monopoly on the dissemination of religious information2, reacted by banning some of the books and publishing its own propaganda including lists of banned books, also the Tyndale Bible written in English was banned in England until Henry VIII broke with the Catholic Church.  An inquisition was directed towards the book publishing capital of Europe, Venice, due to the publication of scientific books which contradicted the beliefs of the Roman Catholic Church.  Books were banned and burned and heresy trials were held.

There were several inquisitions which were heinous affairs that included racial cleansing, torture, and other barbaric acts of terror. These were started before the advent of the printing press but were then directed towards this new threat. Fortunately the inquisitions eventually died out.

It is thought that this transformation in the spreading of ideas, coupled with the previous reintroduction of earlier Greek, Roman and Arabic knowledge fuelled an expansion of scientific understanding which also transformed art in terms of perspective and anatomical representation was a catalyst for the Renaissance.  All of this makes me wonder about the future possibilities of our current era and what similar parallels we could see from that previous “information technology” revolution when the dissemination of information made an exponential leap forward from the old technology, much the same way as we are experiencing an exponential leap forward in information technology.

We now live in an era in which I can download hundreds of books or the equivalent amount of information in minutes more than I can comprehend and software is rapidly evolving to allow me to more effectively deal with large quantities of data I can search, jump, skim, and view almost anything about any subject effectively instantly, the time that it takes to send text, audio, images and video has been reduced almost to the speed of light and that’s how quick we can get real time information from all over the world and from space. We also continuously receive an increasing amount of data from various places in the solar system and even at the edge of the heliosphere. 

The very tools to better manipulate crunch and comprehend large petabyte and beyond data are rapidly being invented and refined, the things that we will be able to do in even the next decade(s) is probably going to be revolutionary for human society in terms of art, science and how we live our lives, the changes are already quite pronounced.  Soon images, audio, and video will be as searchable and easily manipulated as text is now and algorithms enhanced with more and more math will be able to digest all of this and allow us to query it and manipulate it ways we probably can’t even imagine yet.

From the sixteenth century until the end of the twentieth century publishing grew into a vast industry expanding from books to encompass more such as periodicals. Other entire industries were spawned from it such as the newspaper industry.  This spawned new media like audio, radio and recording, movies and video that grew into entire industries.  Then along came the internet and fast data transmission. All of these industries are now under pressure and many are fighting this change.  Now it would be a bit overly dramatic to compare the copyright wars to the inquisition but the parallel is there: large organizations in control of the dissemination of information fighting the change, more egalitarian information access and distribution.  Another common thread is the use of law, the Catholic Church tried to impose its law on the local European governments to stamp out heresy.  We now find ourselves in a similar position with the established media companies using their deep pockets to attempt to write new laws that benefit them at the potential cost to a free internet and innovation, so far legislation like the Research Works Act and SOPA have failed but the fight continues.  Patents especially broad and abstract patents are another threat to innovation this is another system that has been gamed by the big corporations so that it now often does the opposite of the original intent of the founding fathers.

So we now find ourselves at a unique time where there is so much potential for innovation in science and art and hopefully society. These human endeavors are built on collaboration and on the sharing, remixing, and refining of ideas. Many of Shakespeare’s works were derivative of earlier works, can you imagine if the same type of laws and litigation existed then, such works may have never been created.

How this potential innovation will it play out over the next two decades may very well be beyond comprehension, the things I can buy today were the devices of science fiction, specifically Star Trek, when I was growing up, even as a young adult, the idea of having a thousand books on a tablet device or watching real time video from the space station or access to terabytes of data was almost beyond my expectation, yet now I am starting to take it for granted.  My childhood almost seems like the life of a 15th century turnip farmer who could only dream of reading scientific or any knowledge in a book.


1 Much of this is excerpted from Episode 4 of The Day the Universe Changed by James Burke

2The bible and all sermons were held in Latin restricting non-ecclesiastical people direct access religious doctrine.